

model — backed by one or more targets. Each target is one provider model. Targets are tried top to bottom: the gateway sends the request to the first target, and if that target fails in a way another target might not, it sends the same request to the next one. This page explains exactly when that happens and how the gateway keeps traffic away from targets that keep failing. For the most common use of it — running Claude Code on each developer’s own Claude subscription, with a fallback model for when they hit their rate limit — see Get the most out of your Claude subscription.
You need a Barndoor account with admin privileges and the LLM Gateway enabled for your organization. New to gateway administration? Work through the Quickstart Guide first — this page assumes you know your way around LLM Management.
Routes and targets
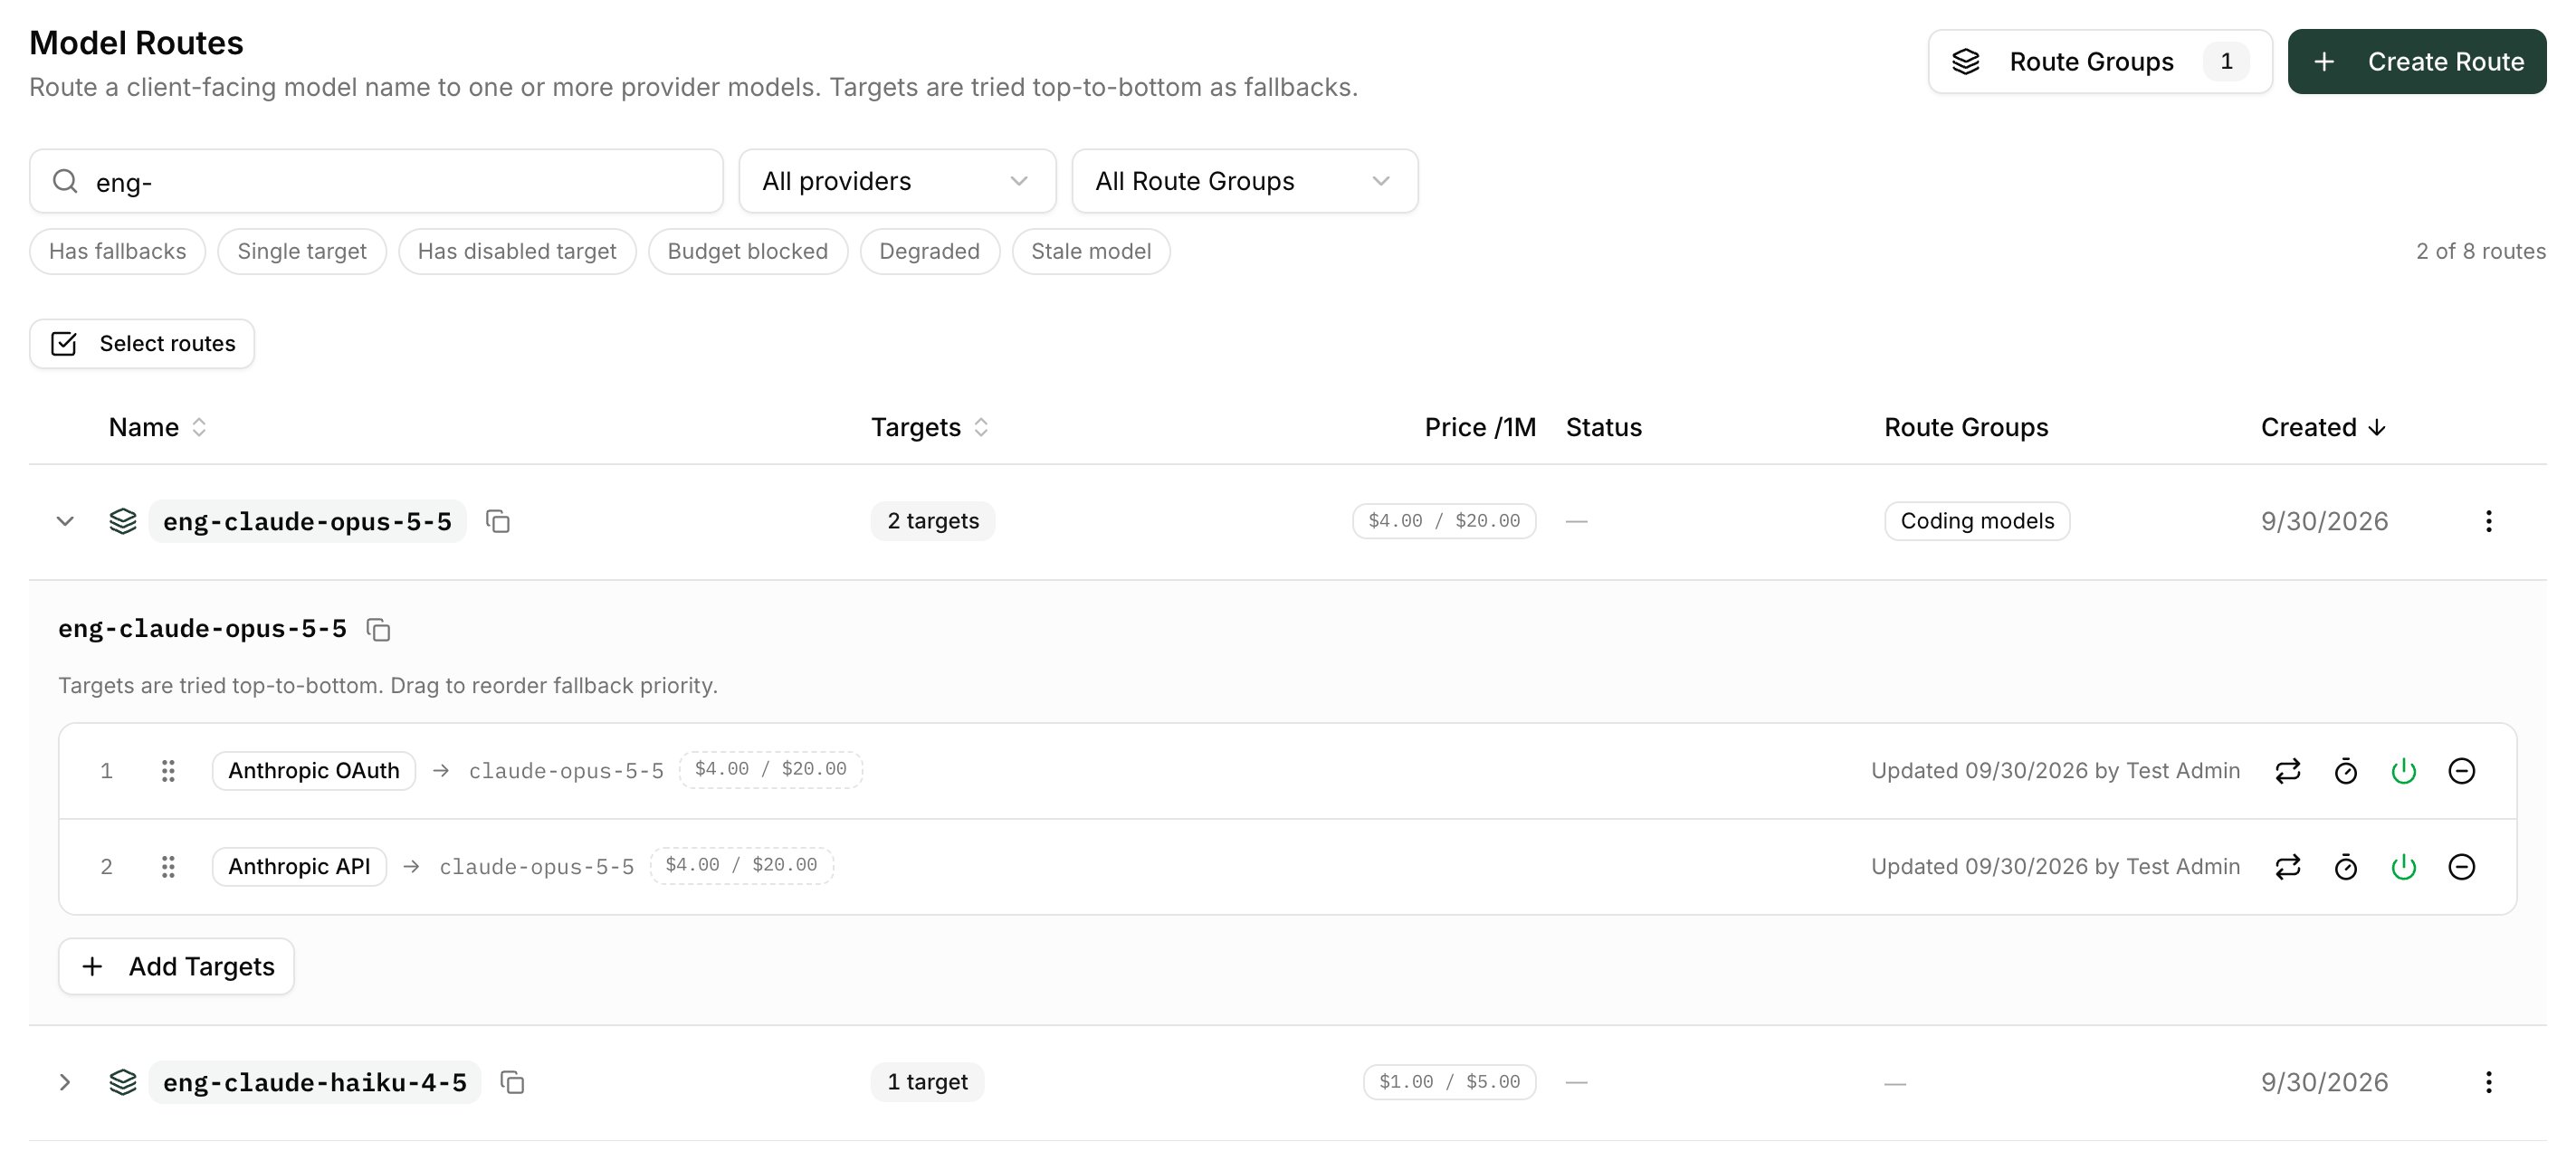
Routes live under LLM Management → Model Routes.- Create Route asks for a Route Name (the name users put in API calls) and one or more provider models to add as targets.
- Expand a route to see its targets, numbered in priority order. Drag a target by its handle to change the order. Add Targets adds more; the row’s actions menu has Rename route, Duplicate route, and Delete route.
- Each target has its own controls on the right of its row:
When the gateway fails over
The gateway moves on to the next target when the current one fails with an error another provider might not share:
Failover happens before the response starts. Once a target has begun streaming a response back, a later failure in that stream is not replayed on another target.
When every target fails, the caller gets one error that lists each attempt under
error.metadata.attempts. Its status is:
401if every target was skipped because the caller’s own credential was rejected;429, withRetry-After, if every target was rate-limited, out of quota, or cooling down;- the shared status if every attempt returned the same one;
- otherwise
502.
Rate-limit retries
By default a rate-limited target fails over immediately. The Rate limit retries popover on each target changes that:- Retry count (0–10) — how many times to retry the same target on a rate limit before failing over.
0means fail over immediately. - Max wait (s) (0–180) — when set, the gateway waits for the provider’s
Retry-Afterbetween retries, up to this many seconds. At0it waits about one second between retries and ignoresRetry-After.
Route health and cooldowns
On top of per-request failover, the gateway tracks the recent results of every target and puts one that keeps failing into a cooldown. While a target is cooling down, requests skip it and go straight to the next target, rather than paying for a failed attempt first. Health is tracked per provider and upstream model, not per route. Two routes that both useclaude-opus-5-5 on the same provider share one health record, so a cooldown triggered through one route applies to both.
What starts a cooldown
Other
4xx responses, including 404, never start a cooldown — the provider answered, it just refused that request.
When a cooldown expires, the target is recovering: the gateway lets a few requests through (three at a time) to test it. After three successes it is healthy again. If a test request fails, the target cools down again — for server failures, for twice as long as last time.
Passthrough providers cool down per user
On a provider using Claude OAuth passthrough or ChatGPT OAuth passthrough, each request carries the caller’s own subscription token. A429 or usage-limit 400 there is that one person’s quota, and a 401/403 is that one person’s token. So those errors cool down only that caller’s credential; the target stays healthy for everyone else. A rejected token cools down for the longest window (300 seconds by default), because it won’t fix itself — the user needs to sign in again.
Server errors, timeouts, and 529 overloaded responses still cool the target for everyone, since they aren’t about any one person’s credential.
Seeing it in the portal
In Model Routes, a target in cooldown shows a badge; hover it for the reason and when it recovers:
A collapsed route shows N of M available when some of its targets are cooling down, or Temporarily unavailable when all of them are. Users see the same badges on their own models under Settings → My Models.
Custom cooldown policies
The thresholds above are per-target defaults. A target whose cooldown policy differs from the defaults shows a Custom cooldown badge; its tooltip lists every value, with the non-default ones in bold:
Cooldown policies are changed through the admin API (the cooldown fields on Create a model route and Update a model route), not in the portal. The Terraform provider does not expose them yet. Because routes to the same upstream model share one health record, each route judges that shared record against its own policy.
Clearing a cooldown
Cooldowns clear on their own: once the window passes, the gateway sends recovery probes and returns the target to service when they succeed. There is no manual reset in the portal — if you need a target back in service sooner (for example, right after fixing a provider-side outage), contact Barndoor support.Route groups
A Route Group is a named set of model routes that a model access policy can target as a whole — for example “Engineering” — instead of listing every route and editing the policy whenever a route is added.- Open Model Routes → Route Groups to create, rename, or delete groups and choose their routes.
- Add routes to a group from a route’s actions menu, or select several routes and add them in bulk.
- A route can belong to several groups. The Route Groups column and filter on the routes list show membership.
Related
- Get the most out of your Claude subscription — a worked example: each developer’s own Claude seat as the primary target, with automatic overflow to a fallback model.
- Routing policies — choose the model per request instead of always starting at the first target.
- LLM Controls — budgets, rate limits, and model access, including how target-bound budgets make a route fail over.