> ## Documentation Index
> Fetch the complete documentation index at: https://docs.barndoor.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Reading the LLM Usage Dashboard
> What each metric on the LLM Usage Dashboard measures — requests, tokens, estimated cost, duration, errors and failovers — and how to read the trends, errors, resilience, caching, by-period and breakdown tabs.
The LLM Usage Dashboard (**Reporting → LLM Usage Dashboard**) reports requests, tokens, estimated cost, duration, errors and failovers for traffic through your LLM Gateway. This page defines what each figure counts, so the numbers can be read — and reconciled against a provider invoice — without guessing.
The dashboard is available to organization admins. It opens on the **Last 7 days**, covering all organization traffic, on the **Trends** tab.
## Choosing the window and scope
Everything on the page — the summary cards, every chart and every table — follows the same time window and the same scope filters.
### Time window
The date button in the header shows the active window and the timezone it's expressed in. Open it to pick a preset (**Last 1 hour** through **Last 30 days**, or **Today**, **Yesterday**, **Week to date**, **Month to date**, **Last month**) or drag a custom range on the calendar. The arrows either side step the window back or forward by its own width.
* **Rolling presets end at "now"** and move forward each time the page refreshes. Stepping the window, or picking dates on the calendar, pins it to fixed start and end times instead.
* **Picking days on the calendar selects whole days**, in the active timezone. Future days can't be selected.
* **The window is part of the URL**, so copying the address shares the exact view. A rolling preset stays rolling for whoever opens the link.
**Refresh** re-fetches the data; **Auto** repeats that every 10 seconds until switched off.
### Timezone
**The dashboard uses UTC by default.** Switch between **UTC** and **Local** (your browser's timezone) at the bottom of the date picker. The choice decides where each day, week and month starts, so it changes which period a request lands in — and therefore the per-period figures — but never the window's totals for the same start and end times.
Keep UTC when comparing against provider invoices, which are almost always denominated in UTC days and months. **Reset** in the date picker restores the default window, granularity and timezone.
### Granularity
The **Hourly / Daily / Weekly** selector sets the length of each period on the charts and in the By period table. It follows the window unless you change it: hourly up to two days, daily up to 90 days, weekly beyond that. Options that would be unreadable for the window are greyed out — hourly over more than eight days, daily under six hours, weekly under 14 days. Weeks start on Monday.
### Scope filters
Two independent filters narrow the whole dashboard. Each is optional, and when both are set they combine — **By Group** "Platform" together with **By Provider** "anthropic" shows only that group's Anthropic traffic.
| Filter | Options | Notes |
| - | - | - |
| **Who** | **All Organization**, **By User**, **By Group**, **By Role**, **By AI Agent**, **By API Key** | **By Group** covers the group's members plus API keys assigned to the group rather than a user. **By Role** covers users only. |
| **What** | **All Models**, **By Provider**, **By Model**, **By Upstream Model**, **By Credential** | The value list offers only values that appear in the current window (and in the **Who** scope, if set). |
Picking a dimension without a value leaves that filter off, so the dashboard never goes blank mid-selection.
**By AI Agent** matches the agent recorded on each request at the time it was made — not the agent's currently bound keys — so an agent's history doesn't change when keys are unbound or rebound. It only appears once API keys can be bound to AI agents in your organization; this may not be enabled for your organization yet — contact Barndoor.
## The summary cards
Seven cards sit at the top, reflecting the selected window and scope.
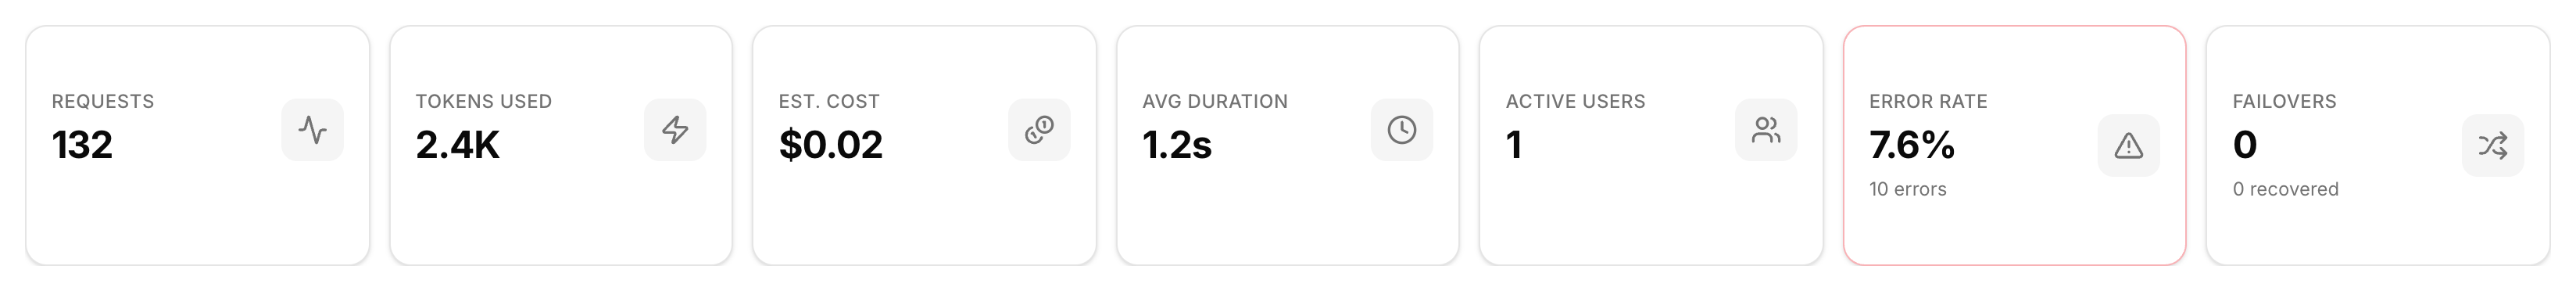 | Card | What it counts |
| - | - |
| **Requests** | Every completed request — successful, failed, or blocked by the gateway |
| **Tokens Used** | Input + output + cache read + cache write tokens |
| **Est. Cost** | Cost recorded on each request, from your model pricing at the time |
| **Avg Duration** | Average time per request, as measured at the gateway |
| **Active Users** | Users active in the busiest single period |
| **Error Rate** | Share of requests that failed or were blocked, with the raw count beneath |
| **Failovers** | Failed provider attempts that the gateway retried on another route, with the requests that were recovered beneath |
**Active Users** is a peak, not a total. It reports the highest distinct-user count seen in any one period, so a window where ten users were each active on a different day shows the busiest day's count rather than ten. Changing the granularity changes it.
### Requests
One row per request that reached an outcome: **success**, **error**, or **denied** (blocked by a budget or rate limit, for example). Blocked requests count here even though they never reached a provider.
Two kinds of traffic count as requests that you might not expect:
* **Routing policy decisions.** When a routing policy uses a model call to pick the route, that call is recorded as a separate request under the same user and key, so one routed user request can add two to **Requests**. Group the Breakdown tab by **Routing Role** to separate them.
* **Routing policy previews.** Each preview an admin runs from the routing policy editor is recorded as a request under that admin, with no API key.
A failover is **not** counted twice: a request that failed on one route and succeeded on the next is one request. The failed attempt is counted in **Failovers** instead.
### Tokens Used
**Fresh input tokens + output tokens + cache read tokens + cache write tokens.**
This is the same basis the cost is computed from, so dividing **Est. Cost** by **Tokens Used** gives a sensible blended rate.
* **Input tokens never include cached tokens**, for any provider. Cache reads and cache writes are counted separately and added on top.
* **Reasoning tokens are already inside output tokens.** Models that "think" before answering bill that thinking as output, and the gateway counts it there. There is no separate reasoning figure on the dashboard, and nothing to add.
* **Blocked and most failed requests contribute no tokens**, since no model produced a response.
### Est. Cost
**The sum of the cost recorded on each request when it was served**, using the pricing rule that applied at that moment. It covers input, output, cache read and cache write cost — including any long-context surcharge on the matching rule.
The figure is *estimated* because it comes from your pricing rules in Barndoor, not from the provider's bill. If your rules match your contract, it should track the invoice closely.
Some requests record **\$0.00**:
* **Unpriced models** — no pricing rule and no Barndoor default covers the model. The request succeeds, but no cost is recorded.
* **Providers with Calculate token cost turned off** — for example a provider billed on a flat subscription. Their tokens are still counted, but cost is recorded as \$0 by design.
* **Blocked requests**, which never reach a provider.
Cost is fixed when the request is served. Changing a price, or a provider's **Calculate token cost** setting, affects only later requests — the dashboard never re-costs history. See [Managing Model Pricing](/how-tos/manage-model-pricing).
If a pricing rule sets no cache rate, cache tokens are costed at the model's normal input rate.
### Avg Duration
**The time the gateway spent on each request**, most of which is time waiting on the upstream provider. It is the whole call's wall-clock — not the overhead Barndoor adds, and not a number to subtract from anything.
Blocked requests, and requests rejected before reaching a provider (for example, an unknown model name), have no duration and are left out.
The card averages each period's average rather than every request. A quiet period counts as much as a busy one, so the card can move when you change the granularity, and one slow call in a quiet hour pulls it up. Treat it as a trend, and read the **Avg Duration Over Time** chart to see when it changed.
It's a mean, not a percentile. Long generations and large prompts take longer by nature, so a shift in the models or workloads behind the traffic moves it too — scope the dashboard to one model to compare like with like.
### Error Rate
Requests with an error **plus** requests blocked by the gateway, as a share of **Requests**. The count beneath the percentage covers both.
A spike is not necessarily a broken provider — it may be a budget or rate limit correctly denying traffic. The **Errors** tab separates the two: each error is attributed either to the **Gateway** (Barndoor's own limits and rejections) or to the **Provider**.
### Failovers
**Failed provider attempts that the gateway retried on another route**, plus, beneath, the number of **requests recovered** that way.
This is separate from **Requests** and **Error Rate**. A provider can be failing badly here while users see no errors, because failover absorbed the failures. The **Resilience** tab shows the detail. See [Failover, Cooldowns, and Route Health](/how-tos/llm-gateway-failover-and-cooldowns).
## The tabs
### Trends
Six charts, one value per period:
* **Requests Over Time**
* **Tokens Used Over Time** — stacked into input and output, plus cache read and cache write when the window used prompt caching
* **Estimated Cost Over Time** — split the same way
* **Avg Duration Over Time**
* **Active Users Over Time** — distinct users in each period
* **Avg Requests per User** — requests ÷ active users in each period
### Throughput
**Peak Requests / min** and **Peak Tokens / min**: the busiest single minute inside each period. Use them to size requests-per-minute and tokens-per-minute [rate limits](/how-tos/use-llm-controls) against real bursts, which an hourly or daily average hides.
Peak Tokens / min counts each request's total as the provider reported it. For some providers that total leaves out cached input tokens, so it isn't on exactly the same basis as **Tokens Used**.
### Errors
Three charts:
* **Error Count by Status Code** — failed requests stacked by HTTP status and who issued it, for example `429 Rate limited · Gateway` versus `429 Rate limited · Provider`. A 429 from the gateway means one of your rate limits fired; a 429 from the provider means the provider throttled you.
* **Error Count by Model** — failed requests stacked by the model the caller asked for.
* **Error Rate (%)** — errors as a share of requests in each period.
The stacked charts show the ten largest series in the window. On low traffic the count and the rate can disagree — a handful of errors is a low count but a high rate. That is expected, and the rate is usually the one to act on.
### Resilience
Retry and failover activity, kept apart from the request figures on every other tab:
* **Provider Failures That Triggered Failover** — failed attempts, stacked by the provider that failed.
* **Requests Recovered by Failover vs Failed on All Routes** — of the requests that hit a failure, how many succeeded on a later route and how many ran out of routes and returned an error.
* **429 Retries Absorbed Within a Route** — rate-limit (429) responses the gateway retried on the same route instead of failing over or returning the error to the caller.
### Caching
This tab only appears when some request in the window used prompt caching. Cache reads (billed at a discount) and cache writes (billed at a premium) are always kept separate, because they move cost in opposite directions.
| Card | What it counts |
| - | - |
| **Cache Hit Rate** | Cache reads ÷ (cache reads + fresh input tokens). Cache writes are not counted. |
| **Cache Savings** | What the cached tokens would have cost as fresh input, at the window's average input rate, minus what they actually cost |
| **Cache Reads** | Tokens served from the cache, with their cost |
| **Cache Writes** | Tokens written into the cache, with their cost |
**Cache Savings can be negative.** Writing to the cache costs more than fresh input, so a workload that writes a lot and reads little back pays more with caching than without it. The card shows "—" when the window has no fresh input cost to compare against.
Beneath the cards, **Cache Hit Rate Over Time**, **Cache Tokens Over Time** and **Cache Cost Over Time** show whether reuse is improving or decaying.
### By period
One row per period — hourly, daily or weekly, chosen from the **Usage by** dropdown — newest first, with requests, input tokens, output tokens, cache read and cache write (when used), **Total tokens**, **Est. cost**, errors and error rate. Totals for the window match the summary cards.
* **Quiet periods are hidden by default.** The line above the table says how many are held back ("5 of 7 days with activity"); clear **Hide quiet days** to show them as zero rows.
* **Expanding a row** breaks that single period down along the dimension set in **Expand to**, so you can go from "Tuesday was expensive" to "Tuesday was expensive on this model" without changing the window.
* **The first and last periods of a window are usually partial.** A **Last 7 days** window starts at the current time of day seven days ago, so its first daily row covers only part of that day.
**Export CSV** downloads exactly the rows and columns on screen, with plain numbers a spreadsheet can sum. The first line records the window and timezone, and the filename carries both, for example `llm-usage-by-period-2026-09-01_2026-09-07-UTC.csv`. Hidden quiet periods are left out of the file too.
### Breakdown
The same traffic grouped along one dimension at a time, chosen from **Group by**, with requests, input, output and total tokens, errors, and estimated cost per row. Cache columns appear when any row used caching; a **Failovers** column appears for Model, Upstream Model and Provider. Switch between table, bar and pie with the toggle above it — the charts show the 15 largest rows by requests.
| Group by | Groups requests by |
| - | - |
| **Model** | The model name the caller sent |
| **Upstream Model** | The provider's own model ID that served the request, with the provider alongside |
| **User** | The user the request was made for |
| **Group** / **Role** | The groups or roles of those users (see below) |
| **Provider** | The provider configuration that served the request |
| **Credential** | The stored provider key that served the request — the unit a provider invoice is billed to |
| **Routing Role** | **User requests**, **Routing overhead** (a routing policy's own route decisions) and **Routing preview (admin)** |
| **API Key** | The gateway API key used, shown as ` ()` |
| **Launch Profile** | The launch profile a `barndoor run` session ran under, shown as ` v` |
| **AI Agent** | The agent recorded on the request |
| **Status Code** | HTTP status, split by whether the gateway or the provider issued it |
| **Error Source** | Failed requests only: **Gateway (Barndoor limits)** versus **Model provider** |
The metric definitions above apply unchanged. A few groupings need more care:
* **Requests with no value for the dimension are left out**, so the rows may not add up to the summary cards. Grouping by **User**, for example, omits traffic from keys not tied to a user.
* **Group and Role can double count.** A user in three groups contributes their full usage to each of the three rows, so group rows can add up to more than the organization total. Users with no group don't appear at all.
* **Routing Role reports all traffic.** **User requests** is everything that isn't a routing decision, so the rows always add up to the total. **Routing overhead** is what routing cost you on top of the requests it routed; **Routing preview (admin)** is spend from admins testing policies, which is not charged to anyone's budget or rate limits. See [Routing policies](/how-tos/llm-routing-policies); they may not be enabled for your organization yet — contact Barndoor.
* **Launch Profile** only has rows if your organization runs agents through `barndoor run` launch profiles, which may not be enabled for your organization yet — contact Barndoor.
* **Credential** is the grouping to use when reconciling against a provider invoice. Several providers can share one credential, so a **Provider** breakdown can split one invoice line across several rows.
* **Status Code** puts a gateway 429 and a provider 429 on separate rows. The Errors column is hidden for **Status Code** and **Error Source**, where it would say nothing new.
#### Traffic excluded from the rows
Three groupings report requests that have no value for the dimension beneath the table rather than as a row, because that bucket is usually the largest and would crowd out the rows that matter. The note beneath the table gives its request and token count, so the rows plus the note reconcile with the summary cards.
| Grouping | The note covers |
| - | - |
| **AI Agent** | Requests with no AI agent assigned: keys not bound to an agent, direct user traffic, and requests from before agent attribution |
| **Credential** | Requests with no credential recorded: requests from before credential attribution, and providers that hold their own key rather than a stored credential |
| **Launch Profile** | Requests not run under a governed agent session: ordinary API-key traffic, and requests from before launch profile attribution |
**Model**, **Upstream Model** and **Provider** rows are grouped by the name recorded when the request was made, so a provider renamed mid-window appears as two rows. **AI Agent**, **Credential**, **API Key** and **Launch Profile** rows are grouped by ID, so a rename keeps one row.
The table returns at most 500 groups, the largest by tokens. Only very broad selections reach that, and grouping by **User** or **API Key** over a long window is the likeliest way to hit it — narrow the window or scope if you need the tail. **Group** and **Role** are built from the user and API key groupings, so they're subject to the same limit.
## Per-agent LLM usage
Each AI agent's detail page (**AI Agents** → select an agent) has an **LLM Usage** card covering the agent's traffic over the page's selected period, with **Cost**, **Requests**, **Tokens Used** and **Error rate**, a cost sparkline, and a **By model** table showing each model's share of the agent's cost.
These use the same definitions as the dashboard: **Tokens Used** includes cache tokens, and usage is matched on the agent recorded on each request, so it doesn't change when keys are unbound or rebound. The "/ day" figures divide by the length of the whole period, including days with no traffic. When the agent has errors, the **Error rate** figure links to this dashboard's **Errors** tab, already scoped to the agent over the same window (up to 30 days).
The card only appears once API keys can be bound to AI agents in your organization; this may not be enabled for your organization yet — contact Barndoor.
## Frequently asked
Est. Cost is computed from your pricing rules at the time each request was served, not read from the provider. It drifts from the invoice when a rule's rates don't match your contract, when models are unpriced or a provider has **Calculate token cost** turned off, or when prices changed partway through the period (history is never re-costed). Check the timezone too: invoices are usually in UTC. To compare like for like, set the window to the invoice period, keep UTC, and group the Breakdown tab by **Credential**. See [Managing Model Pricing](/how-tos/manage-model-pricing).
It includes cache read and cache write tokens, which the input figure never does. Agents that reuse long prompts — coding assistants in particular — can read far more tokens from the cache than they send fresh. The **Caching** tab shows the split.
Requests routed through a routing policy record a second request for the policy's own route decision, and routing policy previews are recorded too. Group the Breakdown tab by **Routing Role** to see how much of the total each accounts for. Blocked requests also count as requests.
Requests blocked by budgets and rate limits count as errors. On the **Errors** tab, check whether the spike is labelled **Gateway** (your own limits) or **Provider**. If failover is configured, the **Resilience** tab shows provider failures that never became user-facing errors.
A user who belongs to several groups is counted in each of them, and users in no group aren't shown. Use **By Group** in the scope filter when you need one group's exact totals.
On a rolling window the first period is partial — the row counts traffic from the start of the window, but expanding it breaks down the whole period, including the part before the window began. Pick whole days on the calendar to avoid this.
On the [MCP Usage Dashboard](/how-tos/read-mcp-usage-dashboard) (**Reporting → MCP Usage Dashboard**). This dashboard covers LLM Gateway traffic only.